curve.fit Help
Use curve.fit to fit a model to your measurements, inspect the result and export a report. You can include uncertainties in x, y or both. To combine repeated measurements of a single quantity, choose Weighted Mean.
Getting started
- Enter your data. Paste from a spreadsheet, type into the table or choose Import File. For a curve fit, put the independent variable in x and the measured response in y.
- Choose a model. Select an equation in the Model panel. Enter initial guesses or fixed parameter values if needed.
- Select measurement uncertainties. Choose Table to use the δx or δy columns, or Expression to enter a constant or percentage. Leave None selected for uncertainties you do not have.
- Press Fit! A new Fit tab shows the fitted parameters, their uncertainties and the plot. Switch between Data and Residuals to inspect the fit, and read any warnings.
- Save your results. Use Single PDF, Double PDF or Browser Report under Export. Return to Setup to change inputs and fit again; completed fits remain available.
For a worked example, choose Walkthrough beside Help or open the Pearson–York example.
Teaching a laboratory course? curve.fit for teaching labs covers the fitting methods, validation, reports and classroom use, with a downloadable PDF and example Pearson–York reports.
On this page: Entering data · Models · Custom equations · Plotting and exports · Sessions · Troubleshooting · Fitting details · Parameter uncertainties · Model uncertainty bands · Weighted Mean · Numerical validation
Guided walkthrough
Choose Walkthrough, then Start practice, to open the guided Pearson example in a separate practice tab. Your original data and saved fits stay in the original tab. The first-visit introduction also offers Take the walkthrough or Continue fitting.
Follow the highlighted controls to fit the sample, inspect residuals, evaluate the model and export a report. Continue becomes available when each action is complete. You can go back, skip a step, choose another chapter or press Escape to close the guide. Closing it leaves the practice results available.
Other chapters cover importing, uncertainty expressions, guesses and fixed values, custom equations, display scales, fit history, exports, Fork and Reset. Some use synthetic teaching data. A preparation button tells you when a chapter needs a fresh practice session. After reloading, choose Walkthrough to resume.
Screen Size
Use a desktop-width window. The data table is on the left; the plot and controls are on the right. The panel arrangement stays fixed; in a narrow window, scroll horizontally to reach the remaining controls. All five parameter rows remain available for custom equations.
Entering Data
Copy and Paste
Copy cells from a spreadsheet and paste them into the data table. Extra rows are added as needed.
Importing Files
Comma-, tab- or semicolon-delimited files can be imported using the "Import File" button on the bottom left. Based on the number of columns in the file, the following will be assumed:
| File columns | Table interpretation |
|---|---|
| 1 | x |
| 2 | x, y |
| 3 | x, y, δy |
| 4 or more | First four columns: x, δx, y, δy |
Move values between columns with cut/copy and paste if needed. Leading header rows are skipped. Select the appropriate uncertainty mode after importing; importing an uncertainty column does not select Table for you. With Weighted Mean selected, a two-column import offers a y/δy mapping.
Imports are limited to 1 MiB, 10,000 data rows and 256 characters per retained cell. Blank rows and leading headers do not count as data rows. A rejected or unreadable file leaves your current data unchanged.
Data Format
Use scientific notation for very large or small values, for example 1.0234e+03. See Number formats for decimal points and commas.
Quick Plot
The plot on the top right updates as you edit complete x/y rows. It displays x and y error bars when Table or Expression uncertainties are selected. You can hover over points to inspect data, or click a point to highlight the relevant row in the table. Empty and incomplete x/y rows are ignored by the preview; complete both values before fitting. Weighted Mean instead previews y measurements against their observation number and uses δy for error bars.
Uncertainties
Select Table to use an uncertainty column, Expression to calculate uncertainties from a rule, or None to leave that uncertainty out of the fit.
To enter expressions, select Expression and enter a constant value or a multiplicative value as a percentage (1%) or a multiple (2x or 2*, for instance). Table uncertainty columns must contain a finite, positive value for every fitted row. The δx and δy columns are shaded when the matching button is not set to Table; their values are kept and editable but not used. Weighted Mean keeps x and δx visible but disables them.
Selecting a Fit Model
Choose a model that describes the relationship you expect in your experiment. The Model panel shows its equation, and the Parameters panel shows the quantities the fit will estimate. Choose Custom Function for another equation, or Weighted Mean to combine measurements of one quantity.
Model notes
Some equations are only defined over part of the number line. Check these restrictions against your data and starting guesses:
| Model | Equation | Note |
|---|---|---|
| Exponential with Offset | Includes a constant vertical offset. | |
| Shifted Reciprocal | Undefined at x = x₀. Keep the fitted range away from that value. | |
| Saturation (Michaelis–Menten) | Undefined at x = −K. | |
| Power Law with Vertical Offset | Use positive x when B is free to take non-integer values. | |
| X Log X | Requires x > 0. | |
| Hill Sigmoid (4 Parameter) | Keep x/C positive when B is free to take non-integer values. | |
| Malus’s Law | Enter angles in radians. |
Starting and Fixed Values
Enter an initial estimate in Guess to help the solver start near a plausible solution. For built-in models, leaving Guess blank lets curve.fit choose a starting value. Check Fix to hold a parameter at the value you entered. A narrow or nearly flat data range may not determine every parameter, even with a good starting guess. Fixing every parameter plots that exact model against your data instead of fitting; the report then shows residuals and the goodness of fit, and every uncertainty is 0. The selected parameter-uncertainty convention uses the number of points minus the number of free parameters when estimating residual scale.
Custom Equations
Select Custom Function and enter an equation using x and coefficients A through E. Omit y =. Parameter names are capitalized and case-sensitive. Write * for multiplication and ** or ^ for powers. For example, A*x**2+B*x+C fits a quadratic.
Use the coefficients in sequence: A and B, for example, rather than A and C. Pasted mathematical minus and multiplication/division symbols are normalized to supported operators. Invalid syntax is highlighted separately from an equation that cannot be evaluated at the starting values.
Typing or pasting coefficients A through E automatically adds the required parameter slots. The − and + buttons beside the model selector remove or add slots manually. After a one-second pause in a complete equation, unused trailing slots are hidden; guesses and fixed settings are retained. Incomplete equations and gaps between used coefficients do not remove slots. Custom equations support the constants pi and π. A floating bubble shown while editing the equation checks syntax and declarations and can offer an explicit correction or a matching built-in model. It never changes a pasted equation or runs a fit for you. Switching shows how starts and fixed parameters map; blank starts use the built-in initializer, and fitting behavior can differ. Undo Model Switch, shown above the Model pane for five seconds, restores model settings without reverting your data or labels. A green Equation OK confirms syntax and parameter declarations, not numerical domain validity or convergence. Keep Custom dismisses that model suggestion for the session; selecting another model and returning to Custom starts a new editing episode.
Typing an opening parenthesis pairs it where the browser supports native undo; typing the matching close moves past the paired close. Rounded literals such as 3.14 may offer Use pi; this precision change is always your choice. Assistance is advisory: it cannot establish that your observations and starting values lie in the equation's domain.
The constants pi and π both mean π; e and tau are not named constants. Scientific notation uses lowercase e, such as 2.3e-4.
The following functions are supported:
- sin
- cos
- tan
- asin
- acos
- atan
- sinh
- cosh
- tanh
- log
- log10
- exp
- sqrt
- sinc
- abs
- floor
- ceil
- erf
- erfc
Plotting and Exports
Labels
The title, x and y label fields in Plot Labels & Axes can be edited in Setup or on a saved-fit tab. They control exported reports; browser plots retain numeric ticks without title or axis-label text. Each axis has independent lin and log controls. These display changes do not rerun the fit. Residual y stays linear so signed residuals and zero remain visible.
The title, x and y label fields support LaTeX syntax by wrapping the LaTeX in dollar signs. For instance, you could write a label as:
Check out this label! $\int_0^\infty x^2 \, \mathrm{d}x$
which would appear as
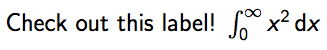
Backslashes and other LaTeX special characters should not be used as plain text outside dollar signs. If a label causes an error, either remove those characters or put a valid LaTeX expression inside $...$.
Fit Results and Outputs
Fit! runs the fit and shows the result right in the page, as a new tab beside Setup. The plot shows the data used for that fit, its fitted curve and confidence band. Data / Residuals controls are overlaid at the plot's upper right on saved fits; Setup has no such switch. The Model, Uncertainties and Plot Labels & Axes panels are below the plot, beside Parameters with the Model Evaluator underneath, and Result with warnings and export controls on the right.
The three most recent fits stay as tabs while you keep fitting; earlier ones are available from Previous. On a fit tab, the data table is greyed and read-only, with grid lines retained. Its rows belong to that saved fit: cutting, editing, pasting or undoing in Setup cannot change a completed fit's table, plot or numerical result. Return to Setup to edit its separate draft.
Each fit tab offers its own exports. Single PDF produces one report. Double PDF produces two side-by-side copies for a pair of lab partners. Browser Report opens the saved fit in a browser page with its plot, full-precision tables and Model Evaluator. Download Data & Fit CSV and Fit JSON from that page. The three workspace export buttons are grouped under Export at the bottom right.
Clicking a PDF button shows a large spinner over its label and temporarily disables the export controls until the report is ready, then opens it in a new tab. If the browser blocks the tab, a compact status near the export buttons offers Details explaining how to allow pop-ups for this site and click the same button again. PDF generation uses the title, labels and scales present when you clicked; subsequent edits cannot change that in-progress report. Browser Report also captures the current title, labels and scales when opened; its image and PDF downloads use those settings. A previously opened report keeps its captured settings, while a saved-fit report link without display settings uses the original labels.
If an export is still pending after the browser finishes waiting, click the same button to check its progress. With the same label and axis settings, this checks the existing request. Each fit permits exports for 32 distinct combinations of label and axis settings; after that, reuse settings from an earlier export or make a new fit.
For both Setup and saved results, the on-screen fit plots leave the X and Y axis labels off. Labels appear in exported reports. Built-in model equations and parameter symbols use the same static artwork in both tabs; custom equations remain text.
Presentation edits and Setup. Each fit keeps its own display settings while the page is open. Edits on the newest fit carry into Setup only for fields you have not independently edited in Setup since that fit was submitted. Clearing a field counts as an edit. Older-fit edits never carry forward, and Setup edits never change saved fits. Reloading restores original stored fit settings; unsaved presentation edits are not recovered. JSON includes effective display settings separately from the original inputs.
Newly generated outputs use the time zone reported by your browser. Opening an older saved output address may show a Preparing fit output page while its report is regenerated; that page refreshes automatically. This compatibility page is separate from the current PDF-button workflow.
Number formats
If your entries contain no commas, curve.fit reads a period as the decimal separator: 1.000 means one, regardless of your browser’s locale.
If entries contain commas, curve.fit uses your browser’s locale. For example, a comma may be a thousands separator or a decimal separator. A period may then mean a thousands separator, so 1.000 can mean one thousand. Check the interpreted values before fitting. The PDF footer records the number-format convention when relevant.
Sessions
This site is based on sessions that hold your data and the settings used to fit and plot it. The eight-character session ID is listed at the bottom of the page. The first visit keeps the main page URL clean; to return to a session or use it on another computer, add its ID to the end of the URL. For instance, the session with ID a08sU3fl can be opened at /a08sU3fl. You can share a generated result by copying its address from your browser.
The browser remembers the current session, so opening the main page in another tab in the same browser normally opens the same session. Use Fork when the open tabs should start with the same data but continue separately, or Reset when the new tab should start blank. The remembered session is shared by tabs in the same browser. To keep two sessions separate across a refresh, open or bookmark each tab at its explicit /SESSIONID address.
Data and fitting settings are saved when you press Fit! (the Enter key also starts the fit while the Fit! button has keyboard focus; elsewhere in the form Enter is reserved for table editing). Unsaved edits exist only in the current page and can be lost if you refresh, close the tab, or navigate elsewhere. PDF buttons open a separate tab once the report is ready; return to the original tab to continue fitting. If you deliberately navigate the fitting tab to an output address, the browser's Back button returns to it. Refreshing or reopening a saved session restores its last selected saved fit, including its table data and fitting settings.
Session Control
Import File is below the frame on the left, the session ID is centered, and Fork and Reset are on the right. Previous is a tab in the row above the plot, alongside Setup and saved fits.
Fork
You can Fork the session you're currently using if you want to keep that session, but copy the data into a new session and continue fitting.
Reset
Reset the session if you want to start fresh or if you want to retain what you have just fit for later. A new session ID will appear and you can still access the old one using the method above. If a new session cannot be created, the previous session is restored and an error message explains what happened.
Previous Versions
The Previous tab, in the row of tabs above the plot, lists every fit completed with that session ID, each with its own fit number, model, and time. A long history is shown a page at a time, with Newer and Older controls below the list; a fit's number is its number in the session, on whichever page it appears. A fit already open in a tab says "already open" instead, and a fit that reported a warning is listed in red, as its tab is. Use Previous to load an earlier saved version's data and settings.
If a Fit Does Not Complete
The error message identifies common input problems and, when possible, selects the field or table cell that needs attention. Check these items first:
- For a curve fit, enter at least two complete rows containing both x and y values, and at least as many points as the number of free fit parameters. More points are needed to estimate an uncertainty scale from residuals. Weighted Mean instead needs at least one y value with its positive δy uncertainty.
- Make sure data, uncertainty, fixed-parameter, and starting-value fields contain valid numbers.
- If Table uncertainties are selected, provide nonzero uncertainties for every fitted row.
- For logarithmic axes and models with restricted domains, make sure the entered x and y values are valid for that model.
- Check that a custom equation uses valid Python syntax, only the parameters shown,
x, and the supported functions listed above. - Put LaTeX in labels inside dollar signs and correct any unmatched braces or other LaTeX syntax.
For a temporary failure or a message that the fit took too long to start, your entries remain on the page. Wait a moment and press Fit! again. If the problem is with a particular input, correct it before retrying. Reset starts a new blank session, so use it only when you no longer need unsaved entries on the current page.
Fitting Details
How the fit is chosen. The δx and δy buttons select one of four fitting problems:
- δx None, δy None: ordinary least squares in y. Every point has equal weight, and the parameter uncertainties are estimated from the scatter of the data about the model.
- δx None, δy given: weighted least squares in y with weights 1/δy².
- δx given, δy None: orthogonal distance regression in which y is treated as exact and only x is allowed to move, so the residual is the horizontal distance to the curve. Internally y receives a negligible uncertainty so the solver stays finite: uniform, positive and data-scaled for both built-in and custom models.
- δx and δy given: weighted orthogonal distance regression. The fit accounts for movement in both coordinates, measured relative to each point’s x and y uncertainties.
For curve models, ordinary or weighted least squares is used when x uncertainties are not selected. ODR is used whenever x uncertainties are selected, including fits with x uncertainties only. Selecting None means no measurement uncertainties are supplied to the fit; it does not mean the measurements are error-free.
What the uncertainties mean. Parameter uncertainties are standard uncertainties (1σ). Their scale is selected in the Uncertainties panel; see Parameter Uncertainties below. With supplied errors the reported metric is reduced chi-squared. Without errors the metric is R² for models linear in their parameters, or sum of squared residuals (SSR) otherwise.
Warnings. "Not full rank" means at least one parameter cannot be determined separately from the others with this data and model; a free parameter whose uncertainty cannot be determined in that case is shown as n/a (in the numerical result it appears as 0), which means not estimable, not exact. Some nearly undetermined parameters instead show a very large uncertainty with the same warning; read it the same way. "Iteration limit reached" means the solver stopped before converging, so treat the result as provisional. A fit with as many points as free parameters has zero degrees of freedom: it cannot estimate an uncertainty scale from residuals. With Absolute, parameter uncertainties may still be available if the parameters are identifiable and measurement uncertainties are supplied. "All parameters fixed" means nothing was estimated: the model with your fixed values is plotted against the data with its residuals and goodness of fit, every uncertainty is 0 because nothing was estimated, and no confidence band is drawn. A fit that does not produce finite numbers, for example a logarithm or power law evaluated at non-positive x, is reported as an error rather than as a result.
Model uncertainty band and calculator. See Model Uncertainty Bands and Standard Uncertainties below for the distinction between covariance scaling, interval width and the Model Evaluator’s propagated 1σ uncertainty.
Parameter Uncertainties
Measurement uncertainties describe the precision of your data. Parameter uncertainties describe how precisely the fit determines quantities such as a slope, decay constant or mean. curve.fit reports parameter uncertainties as standard uncertainties, usually written as .
In the Uncertainties panel, first select Table or Expression for the measurement uncertainties you want to use. Values left in inactive columns are kept but do not enter the fit. Active uncertainties must be finite, positive standard uncertainties, not variances or 95% interval widths. You may need to convert an instrument specification before entering it.
The Absolute and Nominal buttons beside Uncertainties choose whether to use those uncertainty sizes as given or adjust their overall size using the residuals—the differences between data and model. Changing this choice leaves the solver, weights, fitted parameters, residuals and goodness of fit unchanged. It changes parameter uncertainties and, through them, model uncertainty bands and Model Evaluator uncertainties.
Absolute — Do Not Scale Parameter Uncertainties
Use this when your entered values represent independent measurement standard uncertainties in the data's units. For example, an independently established uncertainty of 0.1 V remains the measurement uncertainty even if this particular set of points lies unusually close to the fitted curve.
curve.fit propagates these uncertainties to the parameters without adjusting their overall size to match the residual scatter. It does not simply copy an observation's uncertainty into a parameter's uncertainty, and it does not estimate an additional source of noise.
Absolute does not mean exact. It means the entered uncertainty magnitudes are used as given. A constant such as 0.1 or a percentage such as 5% can specify absolute measurement uncertainties. Here, nominal means that only relative precision is trusted and one common scale is estimated from residuals; it does not mean percentage uncertainties.
Nominal — Scale Parameter Uncertainties Using Residuals
Use this when the measurement uncertainties give the relative precision of your observations, but their overall size is not firmly known. For example, an uncertainty of 0.2 still gives a point one quarter of the weight of a point with uncertainty 0.1. The fit uses the supplied uncertainties to set the relative weights of the points, then estimates a common multiplier from the observed scatter.
With measurement uncertainties selected, parameter uncertainties are multiplied by the square root of reduced chi-squared:
Here n is the number of observations and p is the number of free parameters. Fixed parameters do not count toward p. A reduced chi-squared greater than one increases the parameter uncertainties; a value below one decreases them. If both x and y uncertainties are selected, one common multiplier applies to both axes.
This is the default for every curve.fit model, including Weighted Mean. All earlier curve.fit models used this convention, including custom equations. It is also a common default in other fitting software: SciPy curve_fit uses absolute_sigma=False, lmfit uses scale_covar=True, and Origin enables residual scaling by default. IGOR Pro and Astropy instead treat supplied uncertainties as absolute.
Choosing and saving the setting
Choose the interpretation that matches your measurement uncertainties. Follow the convention specified by your course or experiment. Every model defaults to Nominal, including Weighted Mean. Select Absolute explicitly for the usual propagated uncertainty of a weighted average. With one measurement, Nominal cannot estimate uncertainty from residuals; Absolute propagates the supplied measurement uncertainty.
Without measurement uncertainties entered and selected, only Nominal is available. Removing the last active Table or Expression selection switches to it automatically. Selecting measurement uncertainties again makes both choices available but keeps the current choice. Changing models also keeps the current choice.
Saved fits keep their original choice. Older fits without a recorded choice are treated as residual-scaled. Results tabs show the saved selection in disabled buttons; the information icon beside the buttons still opens the explanation. Browser Report names the choice, and PDFs include it in a footnote. Changing Setup affects the next fit, not a saved result.
Neither option fixes a poor model, outliers, correlated measurement errors or parameters that the data cannot distinguish. Reduced chi-squared can differ from one just by chance, especially with few observations. Check rank and convergence warnings under either choice.
The calculation
Let be the parameter covariance calculated using the supplied measurement uncertainties, before residual scaling. The two choices give:
Each parameter's standard uncertainty is the square root of its diagonal covariance entry:
Neither choice changes your entered measurement uncertainties or forces the reported reduced chi-squared to one. Without measurement uncertainties, residual scaling uses the residual variance instead. This has units of y squared; it is not a dimensionless comparison with error bars.
With zero residual degrees of freedom, there is no scatter-based scale estimate. Absolute can still give uncertainties for identifiable parameters when measurement uncertainties are supplied. It cannot make an underdetermined model identifiable. A one-point Weighted Mean is a supported example.
Model Uncertainty Bands and Standard Uncertainties
The model uncertainty band shows how precisely the data determine the fitted curve. It does not predict where a new measurement will land.
At each x, curve.fit combines the parameter uncertainties and their correlations to calculate the model's standard uncertainty:
Here g contains the model's derivatives with respect to its parameters. The solver uses derivatives analytically for the built-in models, numerically for custom equations.
For curve-fitting models, the plotted band is a 68.27% pointwise confidence interval for the fitted mean response. Its half-width is the model standard uncertainty multiplied by a coverage factor:
- Nominal uses a Student-t factor because the common error scale was estimated from a finite set of residuals. With few degrees of freedom, this makes the band wider than one standard uncertainty. The factor approaches one as the degrees of freedom increase.
- Absolute uses a normal factor because the measurement uncertainty scale is taken as given. At 68.27% coverage this factor is approximately one.
Residual scaling and the coverage factor are separate steps. The reported parameter standard uncertainties do not include a Student-t or normal coverage factor. These confidence intervals are exact for a full-rank linear model with the appropriate independent Gaussian errors, and approximate for nonlinear regression and ODR. Pointwise coverage is not a guarantee for the whole curve at once. An invalid covariance can make the band unavailable.
Example
Suppose the unscaled standard uncertainty of a parameter is 0.10 and reduced chi-squared is 4. Nominal reports ; Absolute reports 0.10. The fitted parameter is the same in both cases. Drawing a confidence interval is a further step that uses the appropriate coverage factor.
If you multiply every active measurement uncertainty by ten, the fitted values stay the same. Absolute then gives parameter uncertainties ten times larger. Under Nominal, that factor cancels against the residual scaling, so parameter uncertainties stay the same. For ODR, this comparison requires multiplying both x and y uncertainties together.
Model Evaluator
Enter x and an optional δx, then choose Calculate beside the Model Evaluator heading. Model Evaluator reports propagated uncertainty. It uses the saved parameter covariance and adds the independent contribution from the evaluation uncertainty δx you enter. That new δx is not multiplied by the residual scale, and the result has no Student-t coverage factor. It does not include measurement scatter or shared systematic errors.
Weighted Mean
Choose Weighted Mean to combine independent measurements of the same quantity. Enter measurements in y and positive standard uncertainties in δy, selecting Table or Expression. The x and δx columns are kept but not used. For a two-column file, choose the y/δy import mapping; the usual two-column import maps to x/y.
The model is , where μ is the weighted mean. Each measurement is weighted by the inverse of its variance. Measurements with smaller uncertainties receive more weight:
The usual propagated uncertainty of the mean is:
Absolute reports this uncertainty without residual scaling. Nominal, the default, multiplies it by , where:
Both choices return the same mean. With equal measurement uncertainties σ, both choices give the arithmetic mean; Absolute gives uncertainty . Identical measurements still give a nonzero uncertainty under Absolute. Residual scaling gives zero uncertainty when the scatter is zero; this does not prove that the measurements are exact.
One measurement is valid. Absolute returns its value and its supplied uncertainty. Nominal returns the mean, but its uncertainty is unavailable because there are no residual degrees of freedom. Reduced chi-squared is unavailable under either choice.
The plot shows observation number on the horizontal axis and measurements on the vertical axis. Vertical error bars show measurement uncertainties; the horizontal band shows the mean ± one standard uncertainty. Residuals are measurement minus mean. There is no Model Evaluator or Model Samples panel because the result is one estimated quantity, not a function of x.
Repeating measurements does not average away a shared calibration offset. Neither option automatically rejects outliers or accounts for correlated errors.